As data labeling for machine learning becomes more automated, the work left for people gets harder.
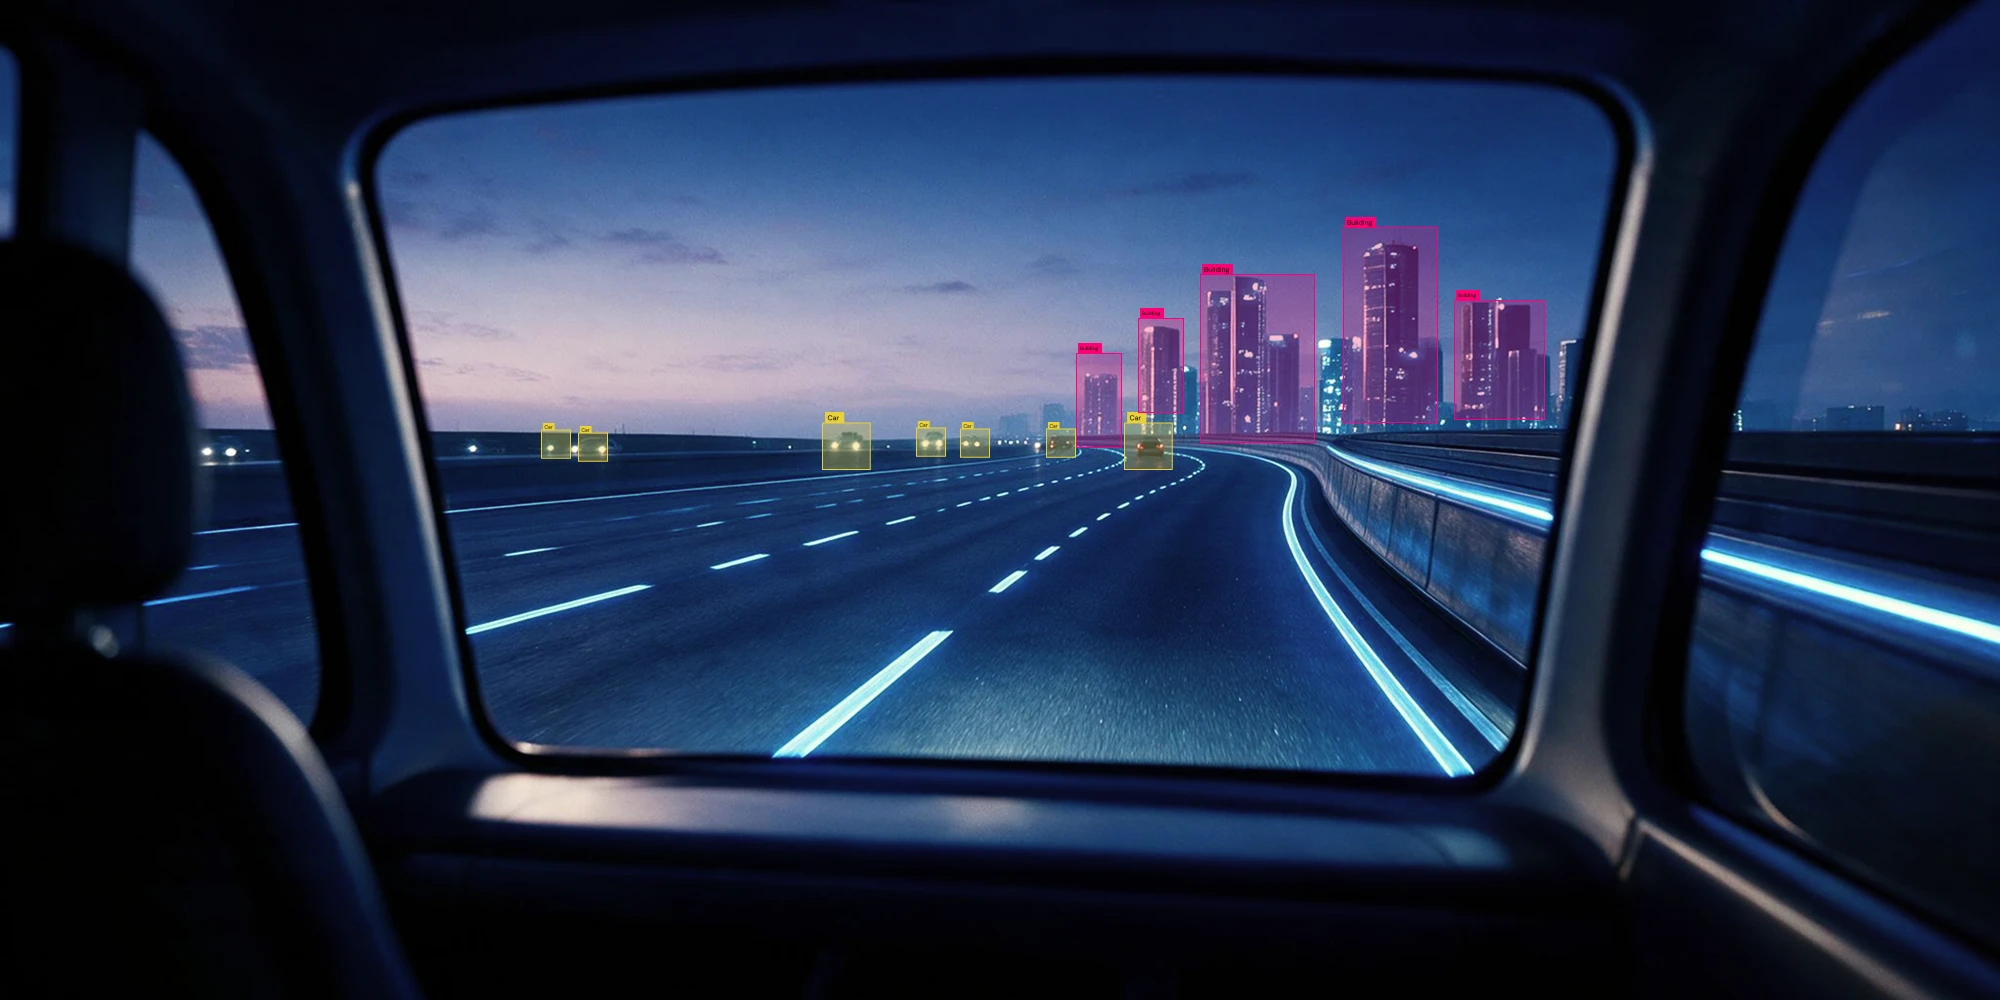
Models can pre-label obvious objects, classify straightforward inputs and generate first-pass annotations at scale. But ambiguous scenes, subjective judgments and rare edge cases still require human judgment.
That shift is changing how data labeling operations are built. Scaling effectively depends on determining where automation works best, where people add the most value and how quality is maintained across the pipeline.
How data labeling works
Data labeling assigns target classes and categories to raw images, text, audio and sensor streams to generate ground truth for model learning. A specialist might label a paved surface as “road,” identify a charging station in a floor map as “dock location” or mark a smooth path as “flat surface.”
These markers help an algorithm interpret data and make more accurate predictions, which is essential to supervised learning; i.e., how a model learns from examples with known answers. During training, the model compares its predictions against the verified label and adjusts its parameters to reduce errors.
Building the data labeling pipeline
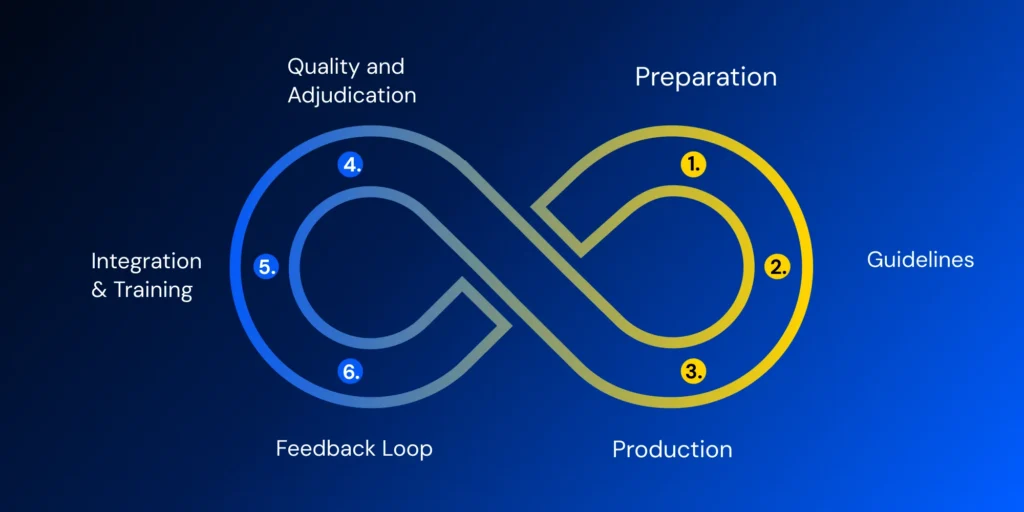
A strong data pipeline starts before anyone applies a label. Teams prepare raw data and develop guidelines that define categories, boundary rules and how to handle ambiguous cases. Visual references and worked examples can help annotators apply those guidelines more consistently.
During production, annotators label incoming data while quality checks surface errors and disagreements for review. Verified datasets are formatted and divided into training, validation and test sets.
But the process doesn’t end when a model deploys. Production errors and new edge cases feed back into the pipeline, helping teams refine guidelines and improve subsequent labeling cycles.
Core data formats and technical demands
The data determines the work. Different tools and expertise are used for labeling an image versus interpreting language, separating voices in an audio stream or identifying anomalies in sensor data. Those differences become more significant as tasks grow more complex.
Computer vision (image & video)
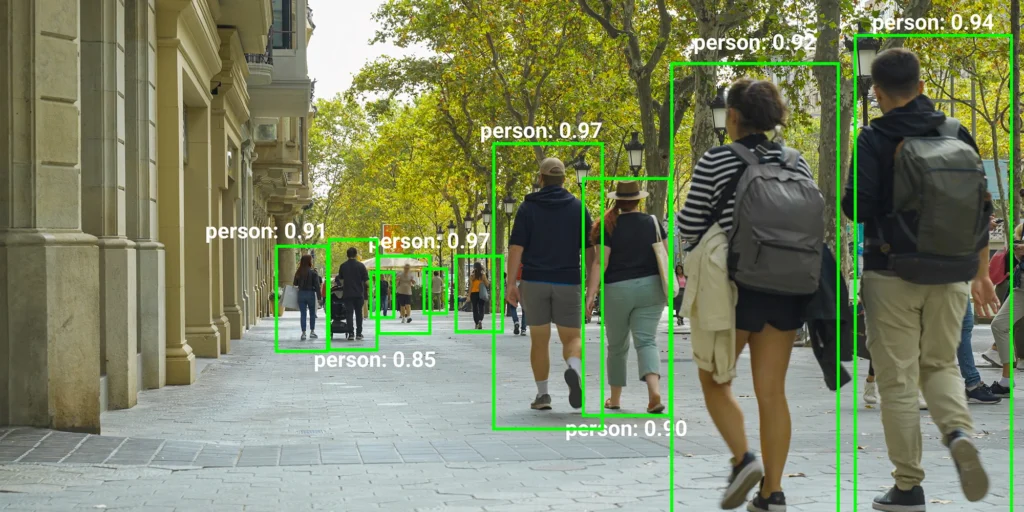
Tasks range from drawing 2D bounding boxes for basic object detection to pixel-level semantic segmentation and temporal tracking across multi-frame video. For spatial tasks, annotators map 3D point clouds and bounding cuboids across camera frames and LiDAR scans.
Text and natural language processing (NLP)
Annotators tag text for named entity recognition (NER), intent classification, sentiment analysis and safety boundaries. Language pipelines can also rely on human feedback and preference data to help evaluate and align generative model outputs.
Audio
Teams produce frame-accurate phonetic transcriptions, perform speaker diarization to separate distinct voices in multi-party audio and classify acoustic events within noisy environments.
Tabular and sensor data
Workflows can involve identifying anomalies across time-series streams, tagging telemetry and combining information across overlapping sensor inputs.
Those differences shape the annotator tools while determining the expertise, oversight and workforce needed for the project.
Aligning delivery models for scale and precision
There is no single workforce model built for every labeling job. The right structure depends on what the data demands: tighter control for sensitive or complex work, greater flexibility when volumes fluctuate or distributed capacity for simpler tasks at scale.
Managed teams, for example, add flexibility, specialized onboarding and domain expertise. Crowd models can expand capacity for high-volume work, with vetted networks adding another layer of quality control and predictability. The other piece of scaling a labeling operation is determining how much of the work needs to be done by people in the first place.
Accelerating production through automation
Automation has the most leverage where the work is repeatable and confidence is high. As ambiguity increases, so does the value of human judgment. The challenge is deciding where to draw that line and moving it as models improve.
Programmatic & rule-based systems: Engineers use scripts and rules to label structured datasets, such as extracting transaction dates and totals from digital receipts. This approach can accelerate repetitive tagging on straightforward files.
Model-assisted labeling & active learning: Models can pre-label incoming data, while active learning techniques prioritize uncertain or informative examples for human review. Clear assets move through faster while ambiguous scenarios, such as foggy night scenes, receive additional human attention.
Generative model-driven pre-labeling: Large vision and language models can draft complex tags, spatial outlines or other first-pass annotations across large datasets, allowing annotators to concentrate on reviewing and correcting outputs.
The goal isn’t to automate every label. Automated methods deliver the greatest value on high-volume, low-ambiguity work. When confidence drops, human review provides the judgment needed to resolve difficult cases while creating feedback that can improve future model performance.
Safeguarding pipelines through quality control
Many labeling errors begin with ambiguity upstream. When categories, boundaries or escalation rules are unclear, even skilled annotators can interpret the same data differently. Those gaps tend to show up in three ways:
- Completeness failures occur when workers omit attributes or lack a structured way to flag ambiguous items.
- Accuracy breakdowns happen when annotators assign incorrect classes or draw imprecise boundaries because guidelines lack sufficient clarity.
- Consistency issues arise when different annotators interpret the same case differently.
Quality controls are designed to catch those issues before they propagate through a dataset. This might take more investment upfront but reduces rework and prevents flawed data from reaching model training:
- Consensus labeling: Routes the same file to multiple workers to identify conflicting judgments and resolve ambiguity.
- Gold-standard verification: Introduces pre-verified questions into active queues to measure ongoing precision.
- Qualification filters: Screen worker capabilities and domain knowledge before granting access to live tasks.
- Anomaly detection: Tracks completion speeds and submission patterns to flag unusual worker activity.
Disagreement can also be useful data. When qualified annotators repeatedly reach different conclusions on the same type of task, the issue may lie in the guidelines rather than the work itself. Those patterns give teams another way to identify where the labeling system needs to improve.
Demonstrating regulatory compliance
The same controls that support model quality can also provide evidence of how training data was created, reviewed and governed.
Under Article 10 of the EU AI Act, providers of covered high-risk AI systems must establish data governance practices for training, validation and testing datasets, including relevant data preparation and annotation processes.
The ISO/IEC 5259 series addresses data quality for analytics and machine learning, including data quality measures, management, processes and governance.
The NIST AI Risk Management Framework (AI RMF) provides a voluntary framework organized around its “Govern, Map, Measure, Manage” functions to help organizations identify and manage AI risks.
Depending on the applicable requirements and governance framework, traceability can include:
- Who labeled each asset and when
- Which version of the annotation guidelines was used
- How inter-annotator disagreements were resolved
- How missing entries and edge cases were logged
Establishing these verification trails during active labeling helps datasets remain traceable and defensible if questions arise later.
Where data labeling goes from here
As models improve, the questions surrounding their training data will keep changing. New environments introduce new edge cases, production exposes gaps that training could not anticipate and each cycle generates information for the next.
Capturing and applying those signals keeps training data aligned with how models actually perform in production. That connection will shape how reliably AI systems improve over time.
Frequently asked questions
The terms are often used interchangeably in practice. When a distinction is made, labeling typically refers to assigning specific category tags, whereas annotation describes richer spatial or structural markup such as segmentation shapes or entity highlighting. Contracts and project scopes generally rely on detailed task specifications rather than specific word choices.
Labeled data pairs raw inputs with target ground-truth answers for supervised learning, where the model learns by example. Unlabeled data contains raw files without target tags and can be used to train unsupervised models or feed active learning systems that select specific items for human labeling.
Pure unsupervised learning does not require labeled training data. Labeled data can still be used to evaluate model performance, benchmark outputs or combine unsupervised methods with supervised or semi-supervised approaches.
The ideal dataset size depends on task complexity, class variance and the underlying model architecture. Fine-tuning an existing foundation model often involves fewer labeled examples than training an architecture from scratch. As production conditions evolve, continuous data collection and labeling become essential to preserving performance.
Ownership depends on the service agreement. Contracts should explicitly define ownership and usage rights across the raw input assets, generated metadata labels and other outputs created during the engagement.


