Speed, scale and output quality dictate the pace of AI development. So much so, this push for velocity is driving up demand for AI data services. Grand View Research projects the global data collection and labeling market will reach $17.10 billion by 2030, expanding at a 28.4% CAGR.
To train machine learning models quickly, companies can leverage crowdsourced data labeling to distribute image, text, audio and video annotation projects across global contributor networks.
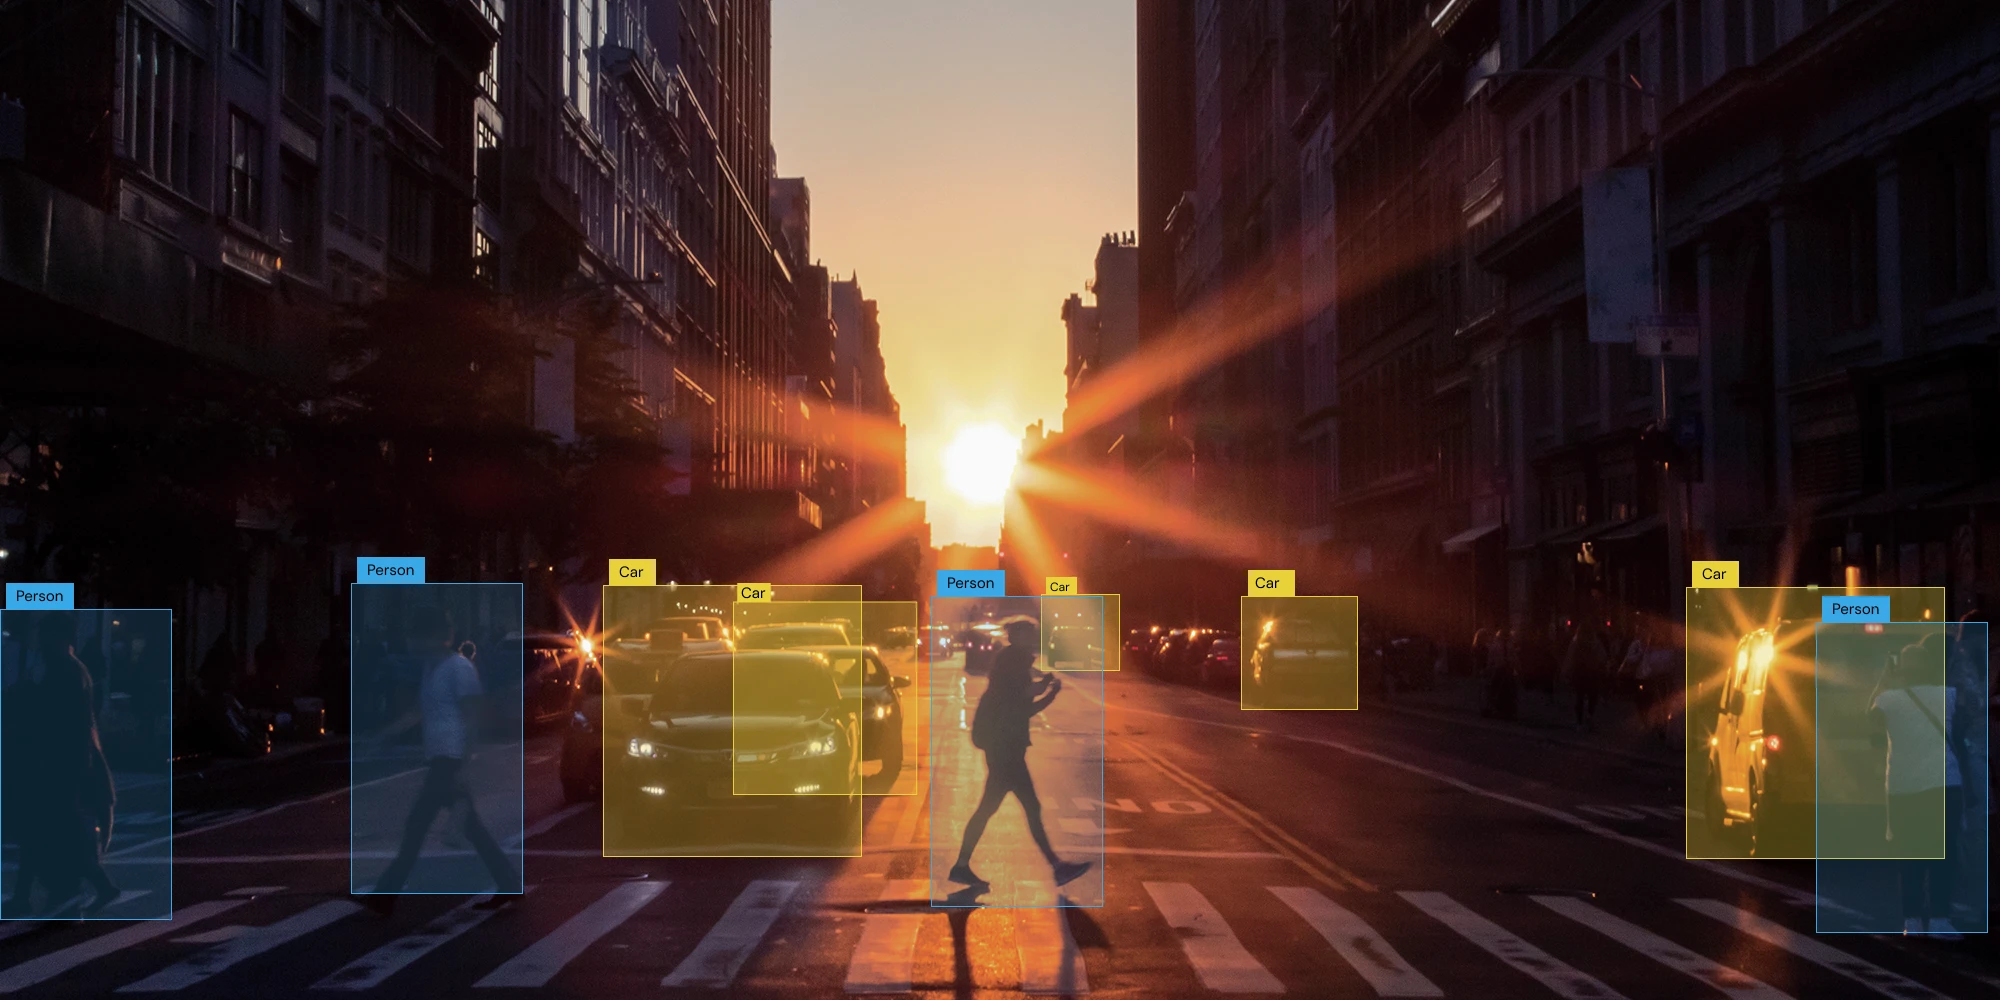
The process requires tight operational control and project/workforce model alignment to ensure dataset integrity and protect downstream model performance.
Data labeling vs. data annotation
While definitions vary, and terms are often used interchangeably, data labeling generally refers to a more specific type of data annotation.
Data annotation is generally the broader process of adding labels, metadata, contextual markings or structured information to raw data so machine learning models can interpret and learn from it. This can include granular tasks like drawing polygon masks around pedestrians in autonomous driving footage, tagging named entities in contracts or evaluating multi-turn LLM responses.
Data labeling often refers more specifically to assigning predefined categories or classes to data — such as marking an image as “Daytime,” identifying a support ticket as “Billing” or categorizing text sentiment as “Positive.” However, the terms are frequently used interchangeably, and their meaning can vary by organization and use case.
Whether training computer vision systems or fine-tuning generative AI models, annotation helps turn raw, unstructured inputs into structured data models can learn from.
Core data annotation types
Annotation methods depend on the file’s format (image, audio, text or video) and the AI application. Each requires different tooling, techniques and workforce skills:
| Media format | Annotation focus | AI applications |
|---|---|---|
| Computer Vision (Image & Video) | Visual boundaries, semantic masks, keypoints and object tags | Spatial perception and autonomous systems |
| Natural Language Processing (Text) | Intent classification, entity recognition and sentiment tagging | Language engines and conversational AI |
| Speech Processing (Audio) | Time-aligned text transcripts and speaker attribution | Speech recognition and voice synthesis |
| Generative AI & LLMs | RLHF preference ranking, prompt-response writing and hallucination tagging | Chatbots, copilot tools and AI agents |
How crowdsourcing drives scale
Crowdsourced data labeling distributes annotation workloads across an expansive network of independent contributors. Typically, teams split datasets into micro-tasks and post them on a central platform. Individual workers complete one task at a time. Automated systems then assemble tagged files into a model-ready dataset.
This model provides flexible capacity to scale annotation volume up or down fast to match development sprints, without fixed labor costs or long hiring cycles. Contributors are usually spread across time zones, keeping data processing active 24/7.
The importance of quality control in training data
At the same time, flexibility has no value if bad inputs contaminate the training set.
Combining automated guardrails with human oversight (human-in-the-loop) helps filter crowd submissions before model ingestion, maintaining data integrity through four primary checks:
- Qualification benchmarks: Requiring annotators to pass domain tests — scored via automated benchmarks and human review — before granting access to live production queues.
- Consensus protocols: Routing identical files to multiple annotators, using ML algorithms to weight agreement based on past reliability, and escalating conflicting answers to human reviewers.
- Gold-standard injections: Automatically blending pre-labeled control items into active worker queues to continuously measure individual accuracy against known ground truth.
- Outlier monitoring: Using AI anomaly detection to flag suspicious completion speeds, mouse movements or submission patterns, sending flagged items to human managers for audit.
Enforcing these hybrid controls upfront is key to preventing manual cleanups and having to rework expensive model retraining down the line.
Matching workforce models to task complexity
While automated checks catch obvious errors, selecting the right workforce model in the first place is the foundation for quality. The optimal approach depends on project volume, task complexity, compliance needs and management preferences.
Models might include:
- Open marketplaces are a good fit when labeling tasks are objective and straightforward, for example, when two annotators naturally reach the same conclusion without prior training or contextual knowledge.
- Vetted crowds provide profiled, pre-screened annotators as tasks become more nuanced.
- Managed teams & in-house reviewers: Offer more oversight for high-stakes, specialized or heavily regulated datasets containing personally identifiable information (PII) or protected health information (PHI).
Crowdsourcing vs outsourcing
Understanding how crowdsourcing and outsourcing work together can help organizations structure the ideal approach for their data pipelines.
Crowdsourcing is more of the delivery mechanism, distributing task volume across a flexible pool of contributors to achieve rapid, global scale.
Outsourcing is usually the management model where companies partner with a specialized provider to handle end-to-end operations, talent sourcing and platform integration.
Direct crowdsourcing typically gives teams complete, hands-on control over flexible capacity.
Partnering with a managed service provider combines that crowd elasticity with dedicated oversight. There’s typically a single-point-of-contact accountability, established quality management and guaranteed delivery SLAs.
Scaling without compromise
Crowdsourcing delivers speed and scale, so long as the right quality controls are in place. Simply put: To scale the AI data pipeline quickly and accurately, pick the right workforce model, vet contributors, enforce automated guardrails and maintain human oversight.
Frequently asked questions
Human-in-the-loop describes a pipeline where automated tools and human annotators collaborate. AI models perform first-pass labeling, while people inspect, correct or validate machine predictions rather than labeling every file manually. This combination lowers overall processing costs while maintaining dataset accuracy.
The ideal volume depends on task complexity, the number of categories to separate and whether the work is done from scratch or fine-tuned. Past a baseline threshold, label accuracy beats sheer quantity. Adding thousands of files containing systematic errors to a dataset trains a system to repeat those mistakes.
Standard enterprise contracts ensure that buyers retain 100% intellectual property rights to all generated labels and output files. Additionally, strict data-handling protocols guarantee confidentiality throughout the project lifecycle.
When evaluating external vendors to manage or augment a data annotation pipeline, check performance across quality, talent verification and compliance. It’s a good idea to work through explicit SLAs, confirm processes for vetting contributors and review regulatory expertise.


